arXiv preprintCHI 2027 under review Context-aware systems Human–AI interaction
Generative Tutorial
Towards Live Contextualized Visual Instructions for Physical Tasks
University of Michigan — * equal contribution
Co-first author, Human Centered Computing Lab, University of Michigan, with Profs. Anhong Guo and Xu Wang
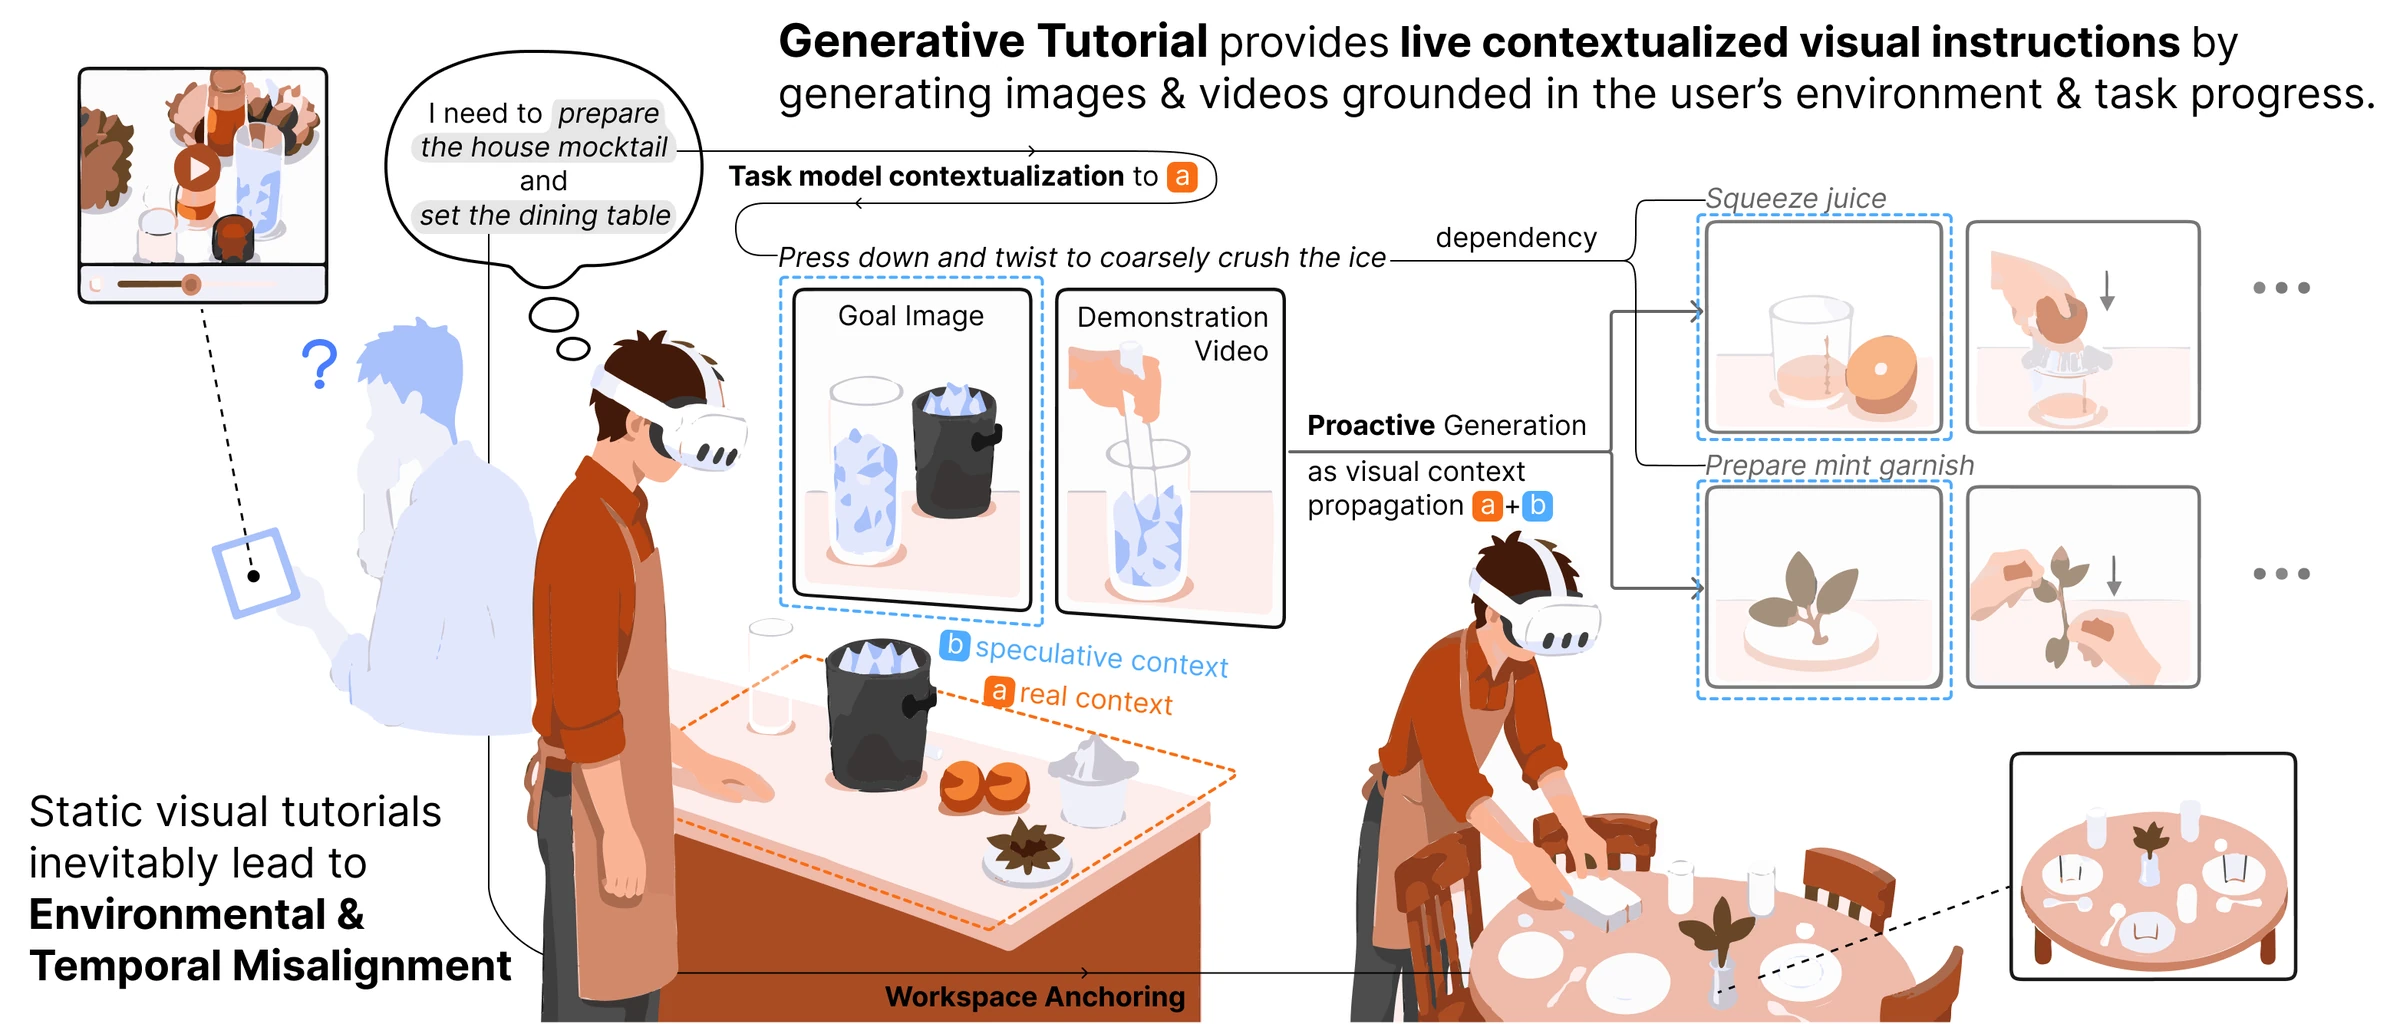
Visual tutorials show us how something should be done — but they are made somewhere else, with someone else’s tools, workspace, and point of view. Following one means first translating what we see into the physical situation in front of us. What if the tutorial started from your world instead, showing what should happen next, right where the task is unfolding?
Generative tutorials are live, contextualized visual instructions generated from the learner’s own environment. Generative Tutorial runs as a loop on a mixed-reality headset.
How it works
- Model the environment. From what the headset sees, it describes the objects in front of you, their states, and how they relate.
- Ground each step. Every step of the task is tied to that model: the objects involved, and what must already be true before the step can begin.
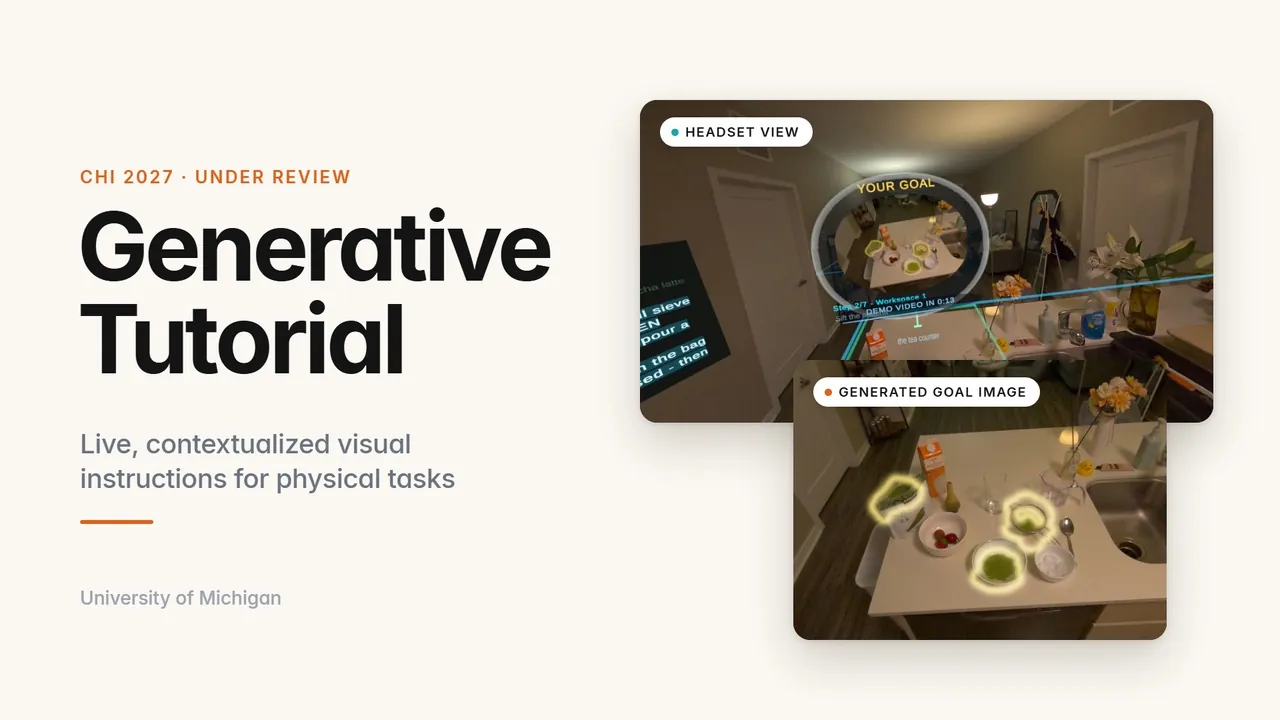
- Generate the instruction. A goal image of your own workspace after the step, with the changes highlighted, plus a short video demonstrating the motion in the same scene.
Richer media take longer to make: text and spatial cues are ready in seconds, a goal image in about fifteen, a video in about forty-five. So guidance for upcoming steps is prepared while you work on the current one — from captured context where the headset can see it, and from predicted context where it can’t: an image of how your counter will look once the current step is done.
The same loop builds guidance from whatever is in front of you — a bouquet, red-bean mochi, a table set for dinner — and reaches past tasks with one right answer to open-ended ones.
User study
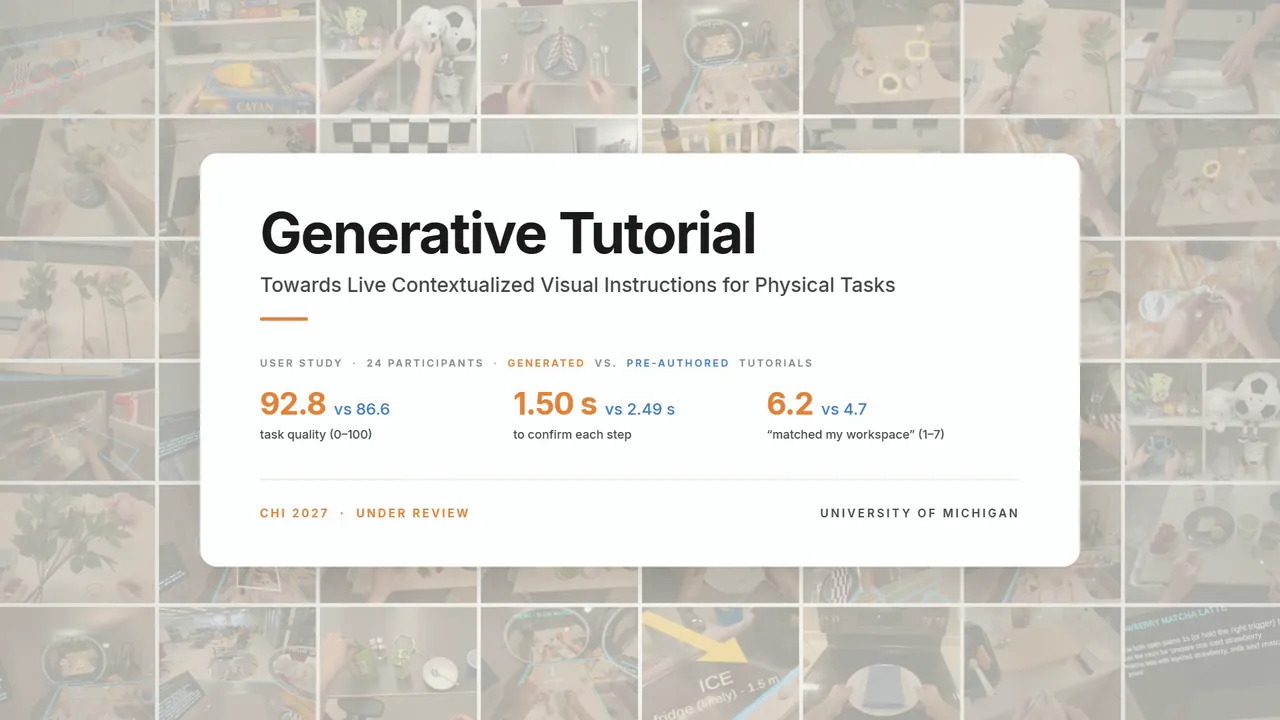
We compared generated and pre-authored guidance in the same interface with 24 participants and four everyday tasks, counterbalanced. With generated guidance, task quality was higher (92.8 vs. 86.6), people confirmed finished steps about a second sooner (1.50 s vs. 2.49 s), and they rated the guidance as a much closer match to their workspace (6.2 vs. 4.7 on a 7-point scale); total time and workload were similar. Generated guidance can also be wrong — an extra bowl, five balls of dough where the text says four — and because everything else matched their table, participants had to decide what was an instruction and what was an artifact.
Videos
Cite
@misc{wu2026generative,
  title         = {Generative Tutorial: Towards Live Contextualized Visual Instructions for Physical Tasks},
  author        = {Wu, Muzhe and Li, Zuchen and Wang, Xu and Guo, Anhong},
  year          = {2026},
  eprint        = {2609.24955},
  archivePrefix = {arXiv},
  primaryClass  = {cs.HC},
  url           = {https://arxiv.org/abs/2609.24955}
}